Notebook
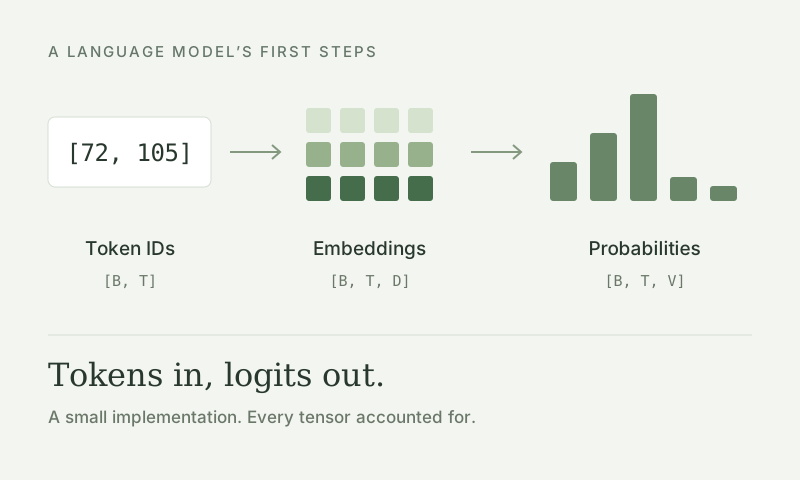
Tokens in, logits out
Build a byte-level BPE tokenizer, trace the path from token IDs to next-token loss, and see what weight tying changes.
The blog
Foundation models, post-training, and the systems behind them. From first principles to working code.
I’m putting together three connected essays. Each will pair the core ideas with derivations, code, and controlled experiments.
From tokens to KV cache
Follow the tensors through tokenization, attention, a modern decoder, training, and cached generation.
This essay is in preparation.
Data, scale, and the move beyond text
A practical map of data pipelines, sparse models, efficient adaptation, multimodality, and evaluation.
This essay is in preparation.
SFT, RLHF, DPO, and GRPO
Derive the objectives, implement the learning loops, and compare the methods under a shared evaluation setup.
This essay is in preparation.
From the workbench
Notebooks and visual explanations, alongside the longer essays.
Notebook
Build a byte-level BPE tokenizer, trace the path from token IDs to next-token loss, and see what weight tying changes.
Visual explanation
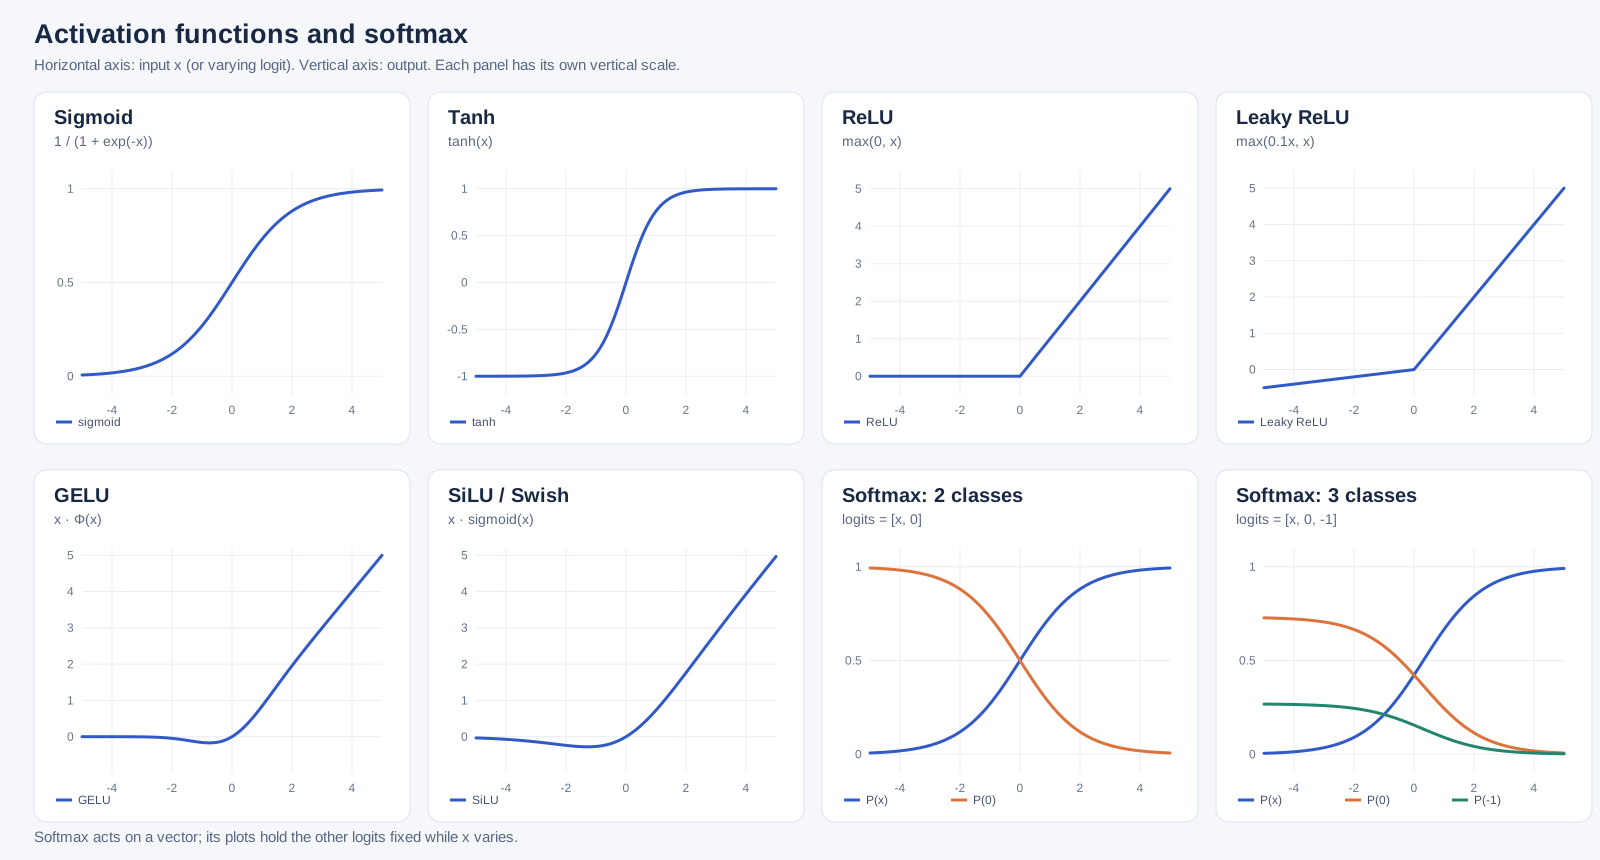
Sigmoid, GELU, SiLU, and softmax, side by side. An illustrated reference for the nonlinearities inside a neural network.